When this is the right tool
- A reporting or read replica in PostgreSQL that must follow a SQL Server system of record.
- A migration with a long cutover: the old SQL Server stays live for weeks and PostgreSQL has to catch up every night until the switch.
- Feeding a PostgreSQL analytics database from one or more SQL Server tables on a schedule.
How a sync works
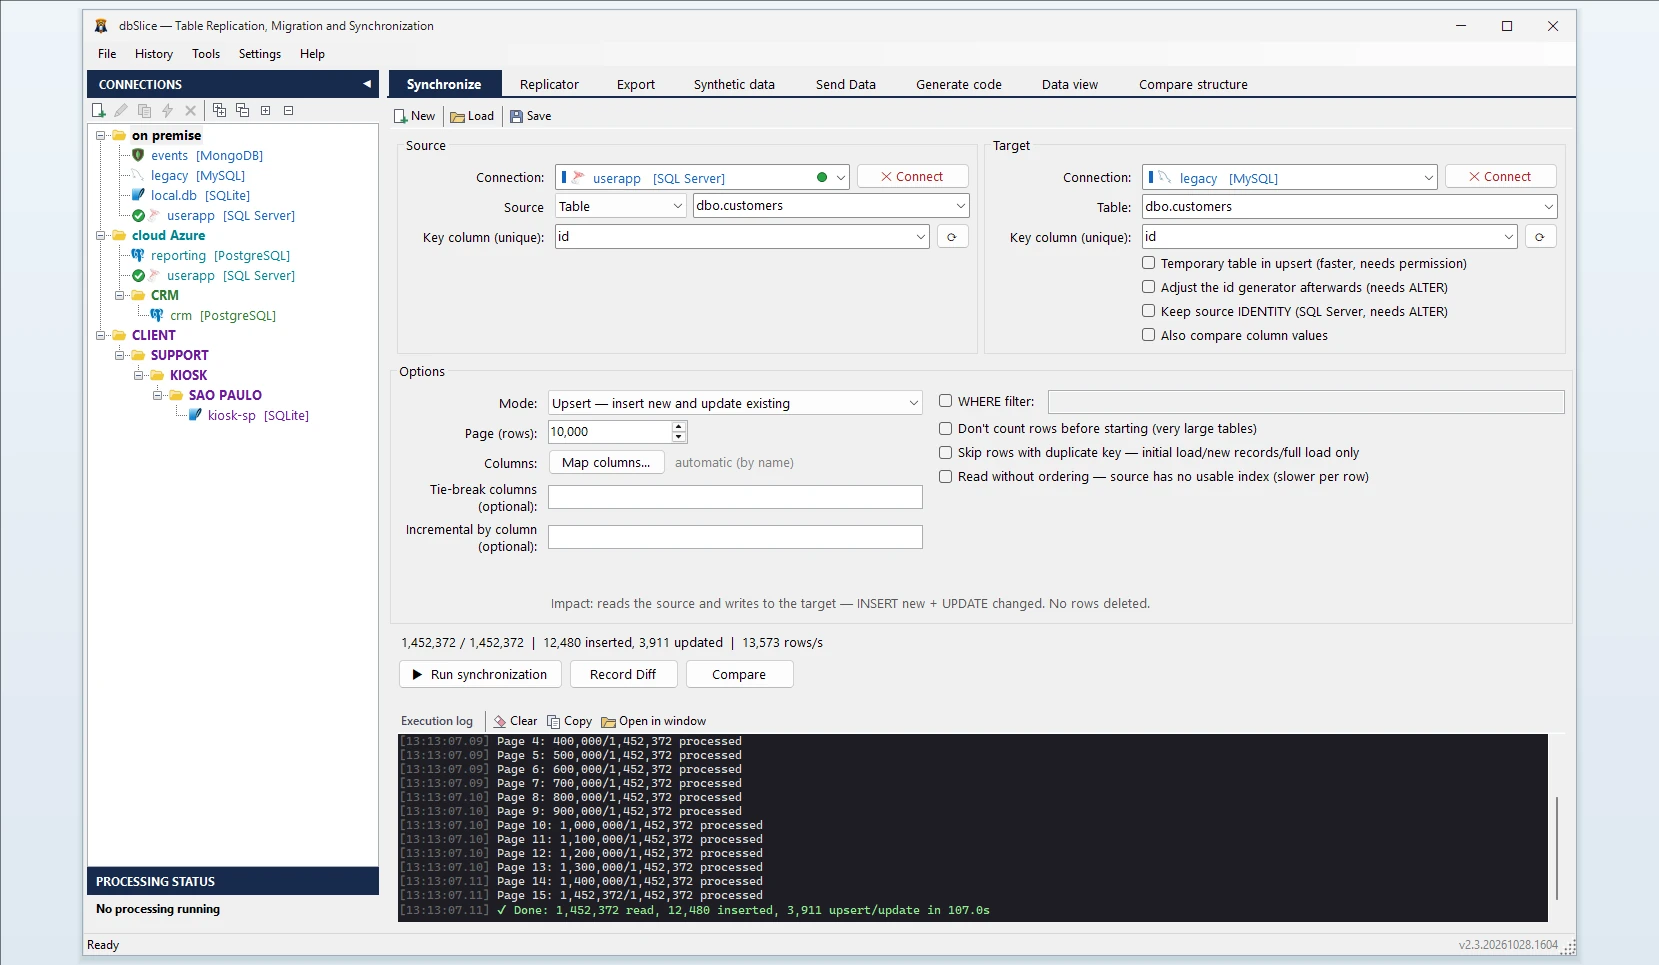
- Pick the source table or a SELECT in SQL Server and the target table in PostgreSQL.
- Choose the key column used to match rows. dbSlice reads the source in small batches, so a live database keeps serving its users while the sync runs.
- Choose what the run does to the target:
Mode What it does Upsert Inserts new keys and updates the ones that changed Insert new Inserts only keys that are missing; existing rows are untouched Initial load Plain inserts into an empty table Update only Updates rows that already exist Full reload Empties the target table and loads it again - Optional: map columns with different names, add a WHERE filter, mask sensitive values in flight.
- Check before writing. Record Diff compares keys on both sides (how many, which are missing).
- Run it, or save it as a job and run it from the CLI or Windows Task Scheduler.
Incremental runs
Point the job at a column that only grows, such as updated_at. For a SQL Server rowversion, use a SELECT source that returns it as CAST(rv AS BIGINT) and point the job at that column. Each run remembers the highest value it read and the next one only reads rows above it. Combined with Upsert, a nightly refresh reads what changed instead of the whole table.
Deletes in SQL Server are not detected by an incremental run. If rows are deleted at the source, schedule a periodic full comparison or a full reload.
Your database stays yours
By default dbSlice only reads and writes rows. It does not create tables, triggers or temporary objects in your databases (the faster write mode below is opt-in). If the PostgreSQL table does not exist yet, dbSlice stops before writing and shows the CREATE TABLE script, translated from the SQL Server schema, for your DBA to review and run.
Speed, with the conditions
Initial loads and full reloads use PostgreSQL's bulk loading. For Upsert and Insert new there is a faster write mode that needs a temporary table for the session; it is off by default and you turn it on only if your DBA allows temporary tables. In our lab test with that mode on (SQL Server 2022 and PostgreSQL 17 on the same host, local container network, no other load, single run per case), dbSlice 2.3 synced:
- 10,000 rows in Upsert mode in 0.4 s (~28,000 rows/s);
- 1,000,000 rows in Insert new mode in 10.6 s (~94,000 rows/s).
Your numbers will differ with network latency between servers, disk, indexes, row width and any masking or transformation. Run the built-in reference test on your own servers before you plan a cutover window.
What dbSlice does not do
- It moves data, not code. Stored procedures, triggers, functions and T-SQL are not converted to PL/pgSQL. Use a code converter for that part and dbSlice for the data.
- It is not real-time replication. Runs are batch jobs (on demand or scheduled). If you need sub-second change capture, look at log-based CDC tools.
Also works for
The same screen syncs between any pair of SQL Server, PostgreSQL, Oracle, MySQL, MariaDB, Firebird, SQLite and InterSystems Caché/IRIS, and PostgreSQL to SQL Server in the other direction. For a one-time move, read the SQL Server to PostgreSQL migration guide. For SQL Server to MySQL or MariaDB, see the dedicated page.